By ShriprasannaPublished July 5, 2026Updated September 26, 2026
Claude Fable 5 Humanizer: Why Detectors Still Catch It (2026)
When Anthropic shipped Claude Fable 5 on June 9, 2026, it didn't undersell it. Anthropic called Fable 5 "a Mythos-class model that we've made safe for general use" and said it "is state-of-the-art on nearly all tested benchmarks of AI capability." It "stays focused across millions of tokens in long-running tasks," and at the highest effort setting it "reflects on and validates its own work" (Anthropic). If you write for a living in 2026, Fable 5 is one of the strongest first drafts you can get your hands on.
So here's the part nobody puts in the launch coverage: none of that makes its writing sound like you.
In its own test, Originality.ai ran 1,000 Fable 5 samples through three of its detector models and caught between 95% and 97.8% of them, even though those models were trained before Fable 5 existed (Originality.ai). Read that again. A brand-new frontier model, versus detectors that had never seen it, and the detectors still caught nearly all of it. Paste Fable 5 output straight into a paper, a client deliverable, or a published article and you should expect it to be flagged.
This is a guide to why the frontier model is still easy to catch, and how to make Fable 5 output read like a person wrote it. Check your school's AI policy first; many allow AI for brainstorming but not for final text.
The capability paradox
You'd think a smarter model would write more like a human. It doesn't, and the reason is worth understanding because it changes how you fix it.
Detectors don't grade writing. They don't care whether your argument is sharp or your prose is elegant. They measure predictability (how likely each word is given the ones around it) and variation, the natural unevenness in how people build sentences. Humans are erratic. We drop a three-word sentence after a long one. We pick a slightly wrong word because it felt right. We double back.
Fable 5 is very good at the opposite: producing the most probable, best-organized next sentence, every time. That's much of the point of it. And that relentless polish is exactly the kind of signal a classifier is tuned to catch. The model's strength, clean, confident, perfectly sequenced prose, is its fingerprint. Fluency isn't humanity, and detectors have known it for a while: Claude has long been hard to catch by feel while still tripping the statistics.
The agent problem nobody's pricing in
Here's what makes Fable 5 different from earlier models, detection-wise: people don't just chat with it. They deploy it.
Fable 5 is designed for long-running work inside an agent harness (Claude Code, managed agents, your own pipeline) where it grinds through multi-step tasks on its own. That's genuinely useful. It also means it produces far more finished text than a model you're babysitting one message at a time. A single agent run can produce documentation, reports, summaries, and emails by the thousand words. And because Anthropic says it validates its own work at the highest effort setting, it's tempting to trust the output and edit less.
More raw output, shipped with less human editing, from one of the most polished writers available. That's a lot of unedited text carrying the same fingerprint.
If you're producing at that scale, rewriting can't be a copy-paste afterthought. It has to sit in the pipeline. And if you're driving Fable 5 from inside Claude itself, you can humanize without leaving the chat over MCP.
What the detectors actually did to Fable 5
The Originality.ai test is the clearest public data we've found, so the specifics are worth it. It generated 1,000 Fable 5 completions across health, news, finance, technology, and arts, then scored them with three of its detector models:
| Originality.ai model | Fable 5 detection accuracy |
|---|---|
| Lite | 95% |
| Turbo | 97.8% |
| Academic | 95% |
Source: Originality.ai.
The headline isn't only the numbers. It's that those models were trained before Fable 5 launched and still generalized to it. New model, same tells.
Two caveats before you lean on it. This is a detector company testing its own product. And the test used only AI-written text, so it tells you how much AI text was caught, not how often human writing gets wrongly flagged. We haven't run Fable 5 text through Turnitin or GPTZero ourselves, so we won't quote numbers for them. If you draft with other models too, our DeepSeek guide covers the same workflow.
Humanizing Fable 5, including agent output
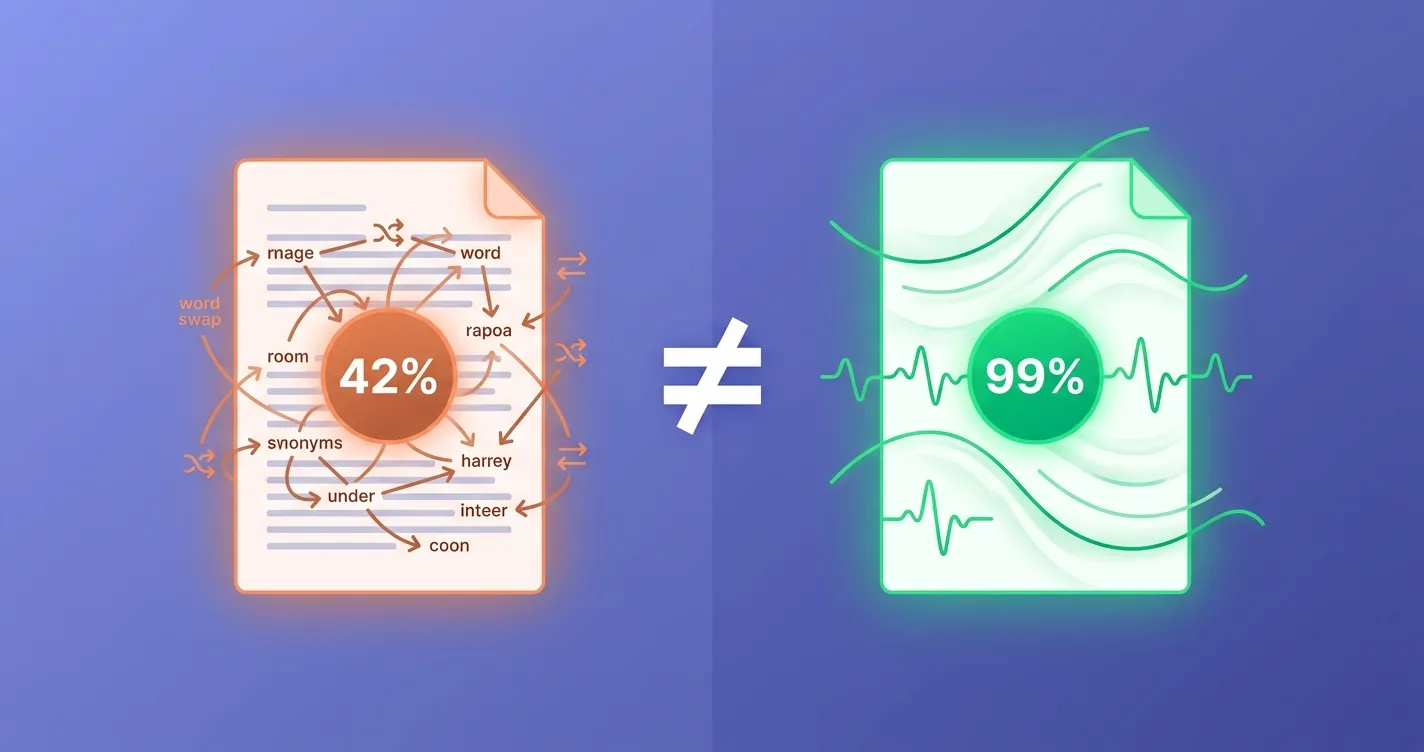
The instinct is to reach for a paraphraser. Don't. Synonym-swapping barely touches the predictability and variation patterns that detectors look at, and on a model this polished it does very little. What you need is a pattern-level rewrite: something that puts human unevenness back in without wrecking Fable 5's meaning or facts.
That's what SupWriter's humanizer is built for. In practice it splits two ways:
- One draft, high stakes: get the draft, fix any factual problems (humanizing won't catch a wrong number), run it through the free humanizer to see the difference on 300 words, then review it yourself.
- Agent or batch output: put rewriting after generation in the workflow, not at the end of a manual copy-paste. Inside Claude Code or a managed agent, the MCP integration lets you rewrite inline so nothing ships unedited.
Either way, add one genuinely human thing the model can't fake: a number from your own data, an actual opinion, a piece of context only you have. Specificity is the signal that's hardest to counterfeit.
Before and after
Fable 5, raw: "The adoption of asynchronous communication has meaningfully improved team coordination. By reducing reliance on synchronous meetings, organizations enable deeper focus, accommodate distributed time zones, and create durable written records of decisions."
Rewritten (an illustrative edit): "Going async fixed our meeting problem. Fewer calls meant more time for focused work, and colleagues in other time zones stopped getting left out. The best side effect? A written record of every decision."
Same claims, including the time-zone point. The second version has a question, sentences of different lengths, and a plainer, first-person voice. That texture is what detectors tend to read as human, and it's precisely what Fable 5 optimizes away.
Check it before it ships
Don't take anything on faith, a humanizer's output included. Detectors disagree with each other and update constantly, so run the actual text you're about to submit through an AI detector first. SupWriter's detector gives you a quick pre-check: one score from a single scoring model, with sentence highlights. It's not a poll of other detectors and not the tool your reader uses, and no tool can guarantee a result (how we test). Anything that still reads as flagged gets another pass. And remember detectors are wrong in both directions, which is the whole reason you check the specific words going out the door instead of trusting a general reputation.
FAQ
Is Claude Fable 5 content really detectable? Yes, on the evidence we've seen. Originality.ai's own test caught 95–97.8% of 1,000 Fable 5 samples. Fable 5's writing is consistently polished and predictable, which is the kind of pattern detectors are built to notice.
Does Fable 5's safety routing change detection? Some requests get answered by Claude Opus 4.8 instead of Fable 5. Anthropic says that when Fable's classifiers "detect a request related to cybersecurity, biology and chemistry, or distillation, the response is automatically handled by Claude Opus 4.8 instead," and that more than 95% of Fable sessions involve no fallback at all (Anthropic). So a document can occasionally mix two models' output. It doesn't help: both read as AI to a detector. Rewrite the finished text regardless of which model wrote which paragraph.
Will humanizing wreck the quality? A good humanizer keeps meaning, facts, and structure and changes rhythm and word choice, so you keep Fable 5's substance and lose the machine cadence. A cheap paraphraser is the thing that actually degrades quality. Either way, read the result before you use it.
Is this against Anthropic's terms? It can be. Anthropic's Usage Policy prohibits using its products to "Plagiarize or submit AI-assisted work without proper permission or attribution" (Anthropic Usage Policy). So if your class, client or publisher hasn't allowed AI help, rewriting Fable 5 output doesn't make submitting it acceptable under either set of rules. Where AI assistance is permitted and credited as required, editing the draft so it reads like you is ordinary editing.
Fable 5 writes one of the strongest first drafts available. SupWriter helps make it sound like it came from you. Humanize your first 300 words free — no credit card required.
Make an AI-assisted draft sound like you
Rewrite stiff, AI-sounding passages in a natural voice.
Free account, no card · 300 free words
Related Articles
Is Using an AI Humanizer Cheating? When to Disclose AI Assistance
What Is an AI Humanizer (and What It Is Not)
AI Words to Avoid in 2026: "Delve" Is Dead — Here's What Detectors Flag Now